Shared Concepts · Hardware · 2026-09-18
The Basic Operations of Collective Communication
Compare Send/Recv with collectives, then follow the inputs and outputs of Broadcast, Scatter, Gather, and Reduce.
How GPUs Communicate followed the process of preparing data, requesting send and receive operations, and using the completed result. Send and Recv each specified a peer to send data to or receive data from.
When multiple GPUs compute together, however, they may need to share the same data or collect their results in one place. We could construct individual transfers, but we can also directly request what result the whole group should produce from its inputs. This is collective communication.
This article first compares these two ways of requesting communication. It then contrasts Broadcast, which copies the same data, with Scatter, which distributes different chunks, and distinguishes Gather, which collects chunks, from Reduce, which combines corresponding values. The key is to track which GPU holds which data before and after each operation.
From Individual Transfers to a Group Operation
Suppose four GPUs are working together. Only GPU 0 currently holds [1, 2], and the other GPUs need the same data.
With Send/Recv, we request transfers from GPU 0 to GPUs 1, 2, and 3, and corresponding receives from GPU 0 at each peer. The developer connects each sender to its receiver.
For a collective, we first define a communication group: the participants that will communicate together. Each participant has a rank, a number identifying it within the group. Here, one process manages one GPU, and ranks 0–3 manage GPUs 0–3 respectively.
Requesting that this group “copy GPU 0’s data so everyone has it” is Broadcast. The participant supplying the original data is called the root. GPU 0 is the root in the figure.
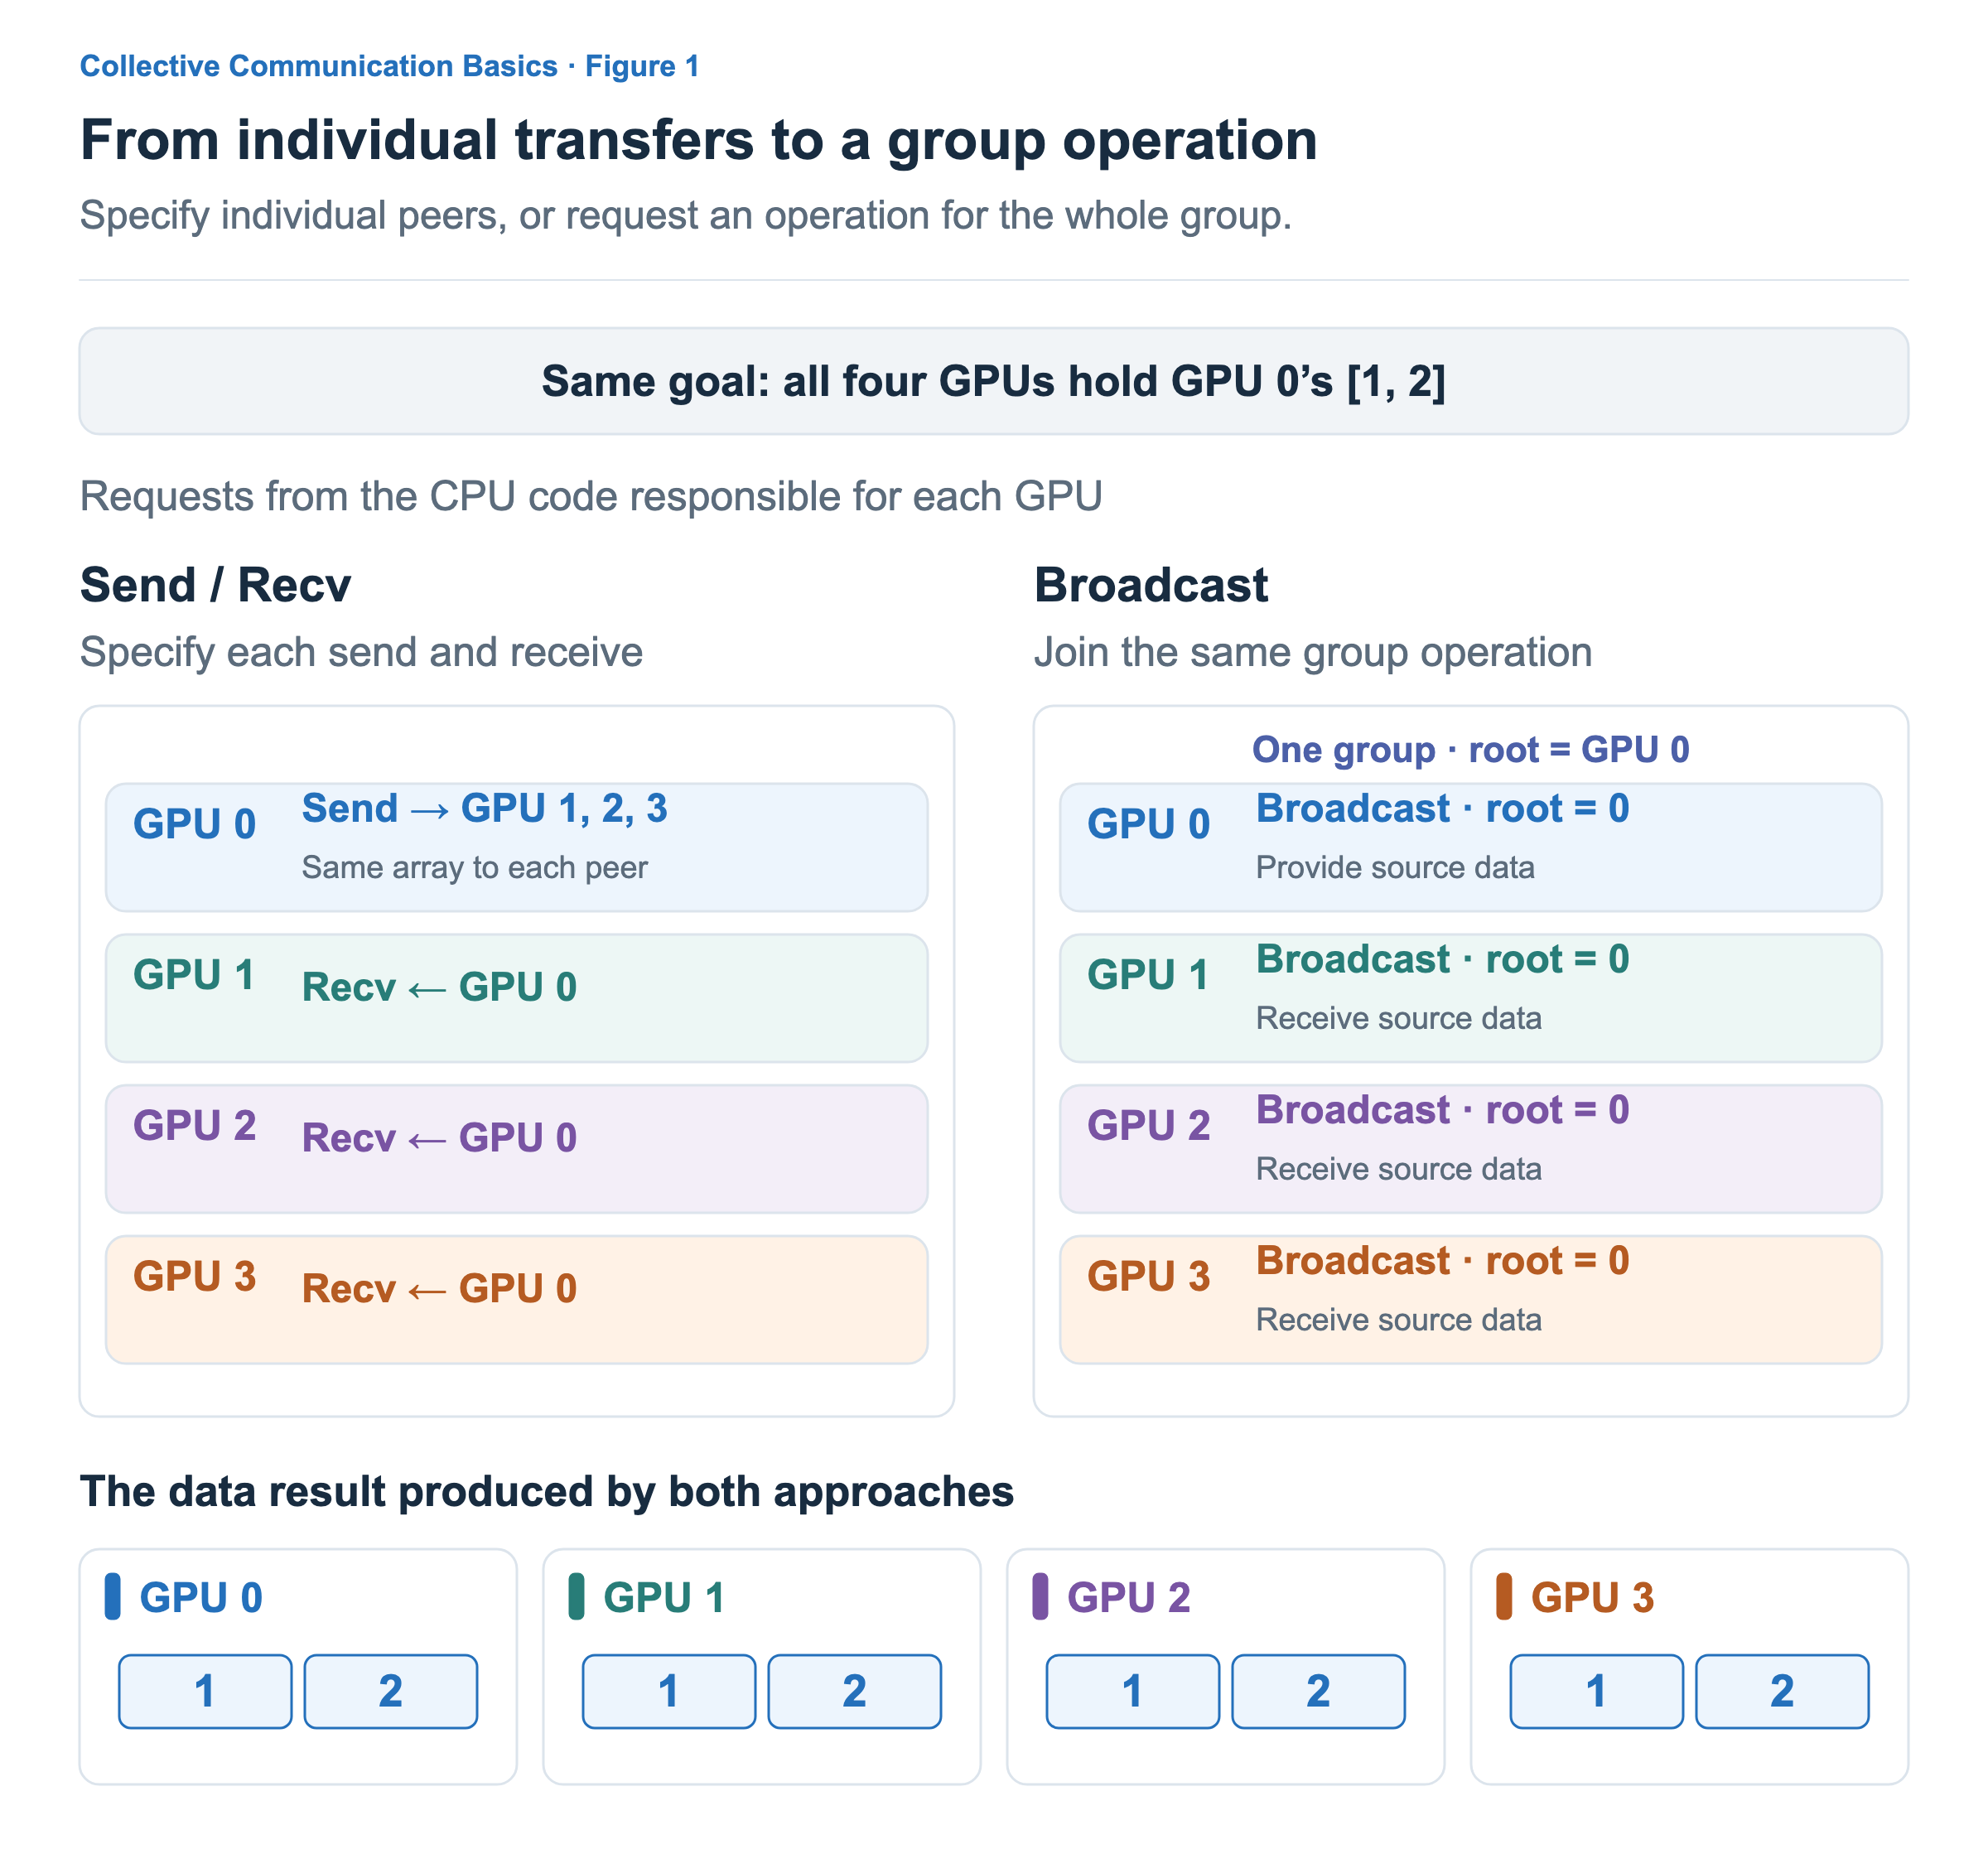
On the left, each CPU program specifies its communication peers. On the right, all four CPU programs participate in the same group’s Broadcast, agreeing that GPU 0 is the root. The names in the figure identify request types. You do not need to understand code syntax: compare requesting whom to send to and receive from with requesting an operation for the group.
A collective does not mean that one request from one CPU automatically involves every GPU. In this example, the CPU program managing each GPU must participate in the same collective. The operation, root, data type, and size must also match. If one participant waits for Broadcast while another waits for Reduce, the intended communication cannot proceed. NCCL collective communication guide
The distinction is therefore not the number of GPUs. Two GPUs can perform a collective, and many GPUs can use individual Send/Recv transfers. Combining Send/Recv can also produce the same result as Broadcast. With a collective, the developer expresses the group’s operation, and the communication library determines how to carry it out. NCCL Send/Recv guide
Participating together also does not mean that CPUs must call the function at precisely the same instant or that all GPU work stops. As with the communication discussed earlier, distinguish the CPU request from actual GPU completion. Work that consumes the result must be ordered after the relevant communication completes. NCCL and CUDA streams
We will now focus on inputs and results rather than individual requests. The following figures show separate input and output buffers for clarity. A central box represents the group operation; it does not mean that data must pass through a central device.
Broadcast: Sharing the Same Data
Broadcast gives every participant the root’s data. For example, it can distribute common settings or an array prepared on one GPU to the others.
Suppose GPU 0 holds [1, 2]. After broadcasting this array, GPUs 0, 1, 2, and 3 all hold [1, 2]. Each participant receives a copy of the whole array, rather than a subset of its elements.
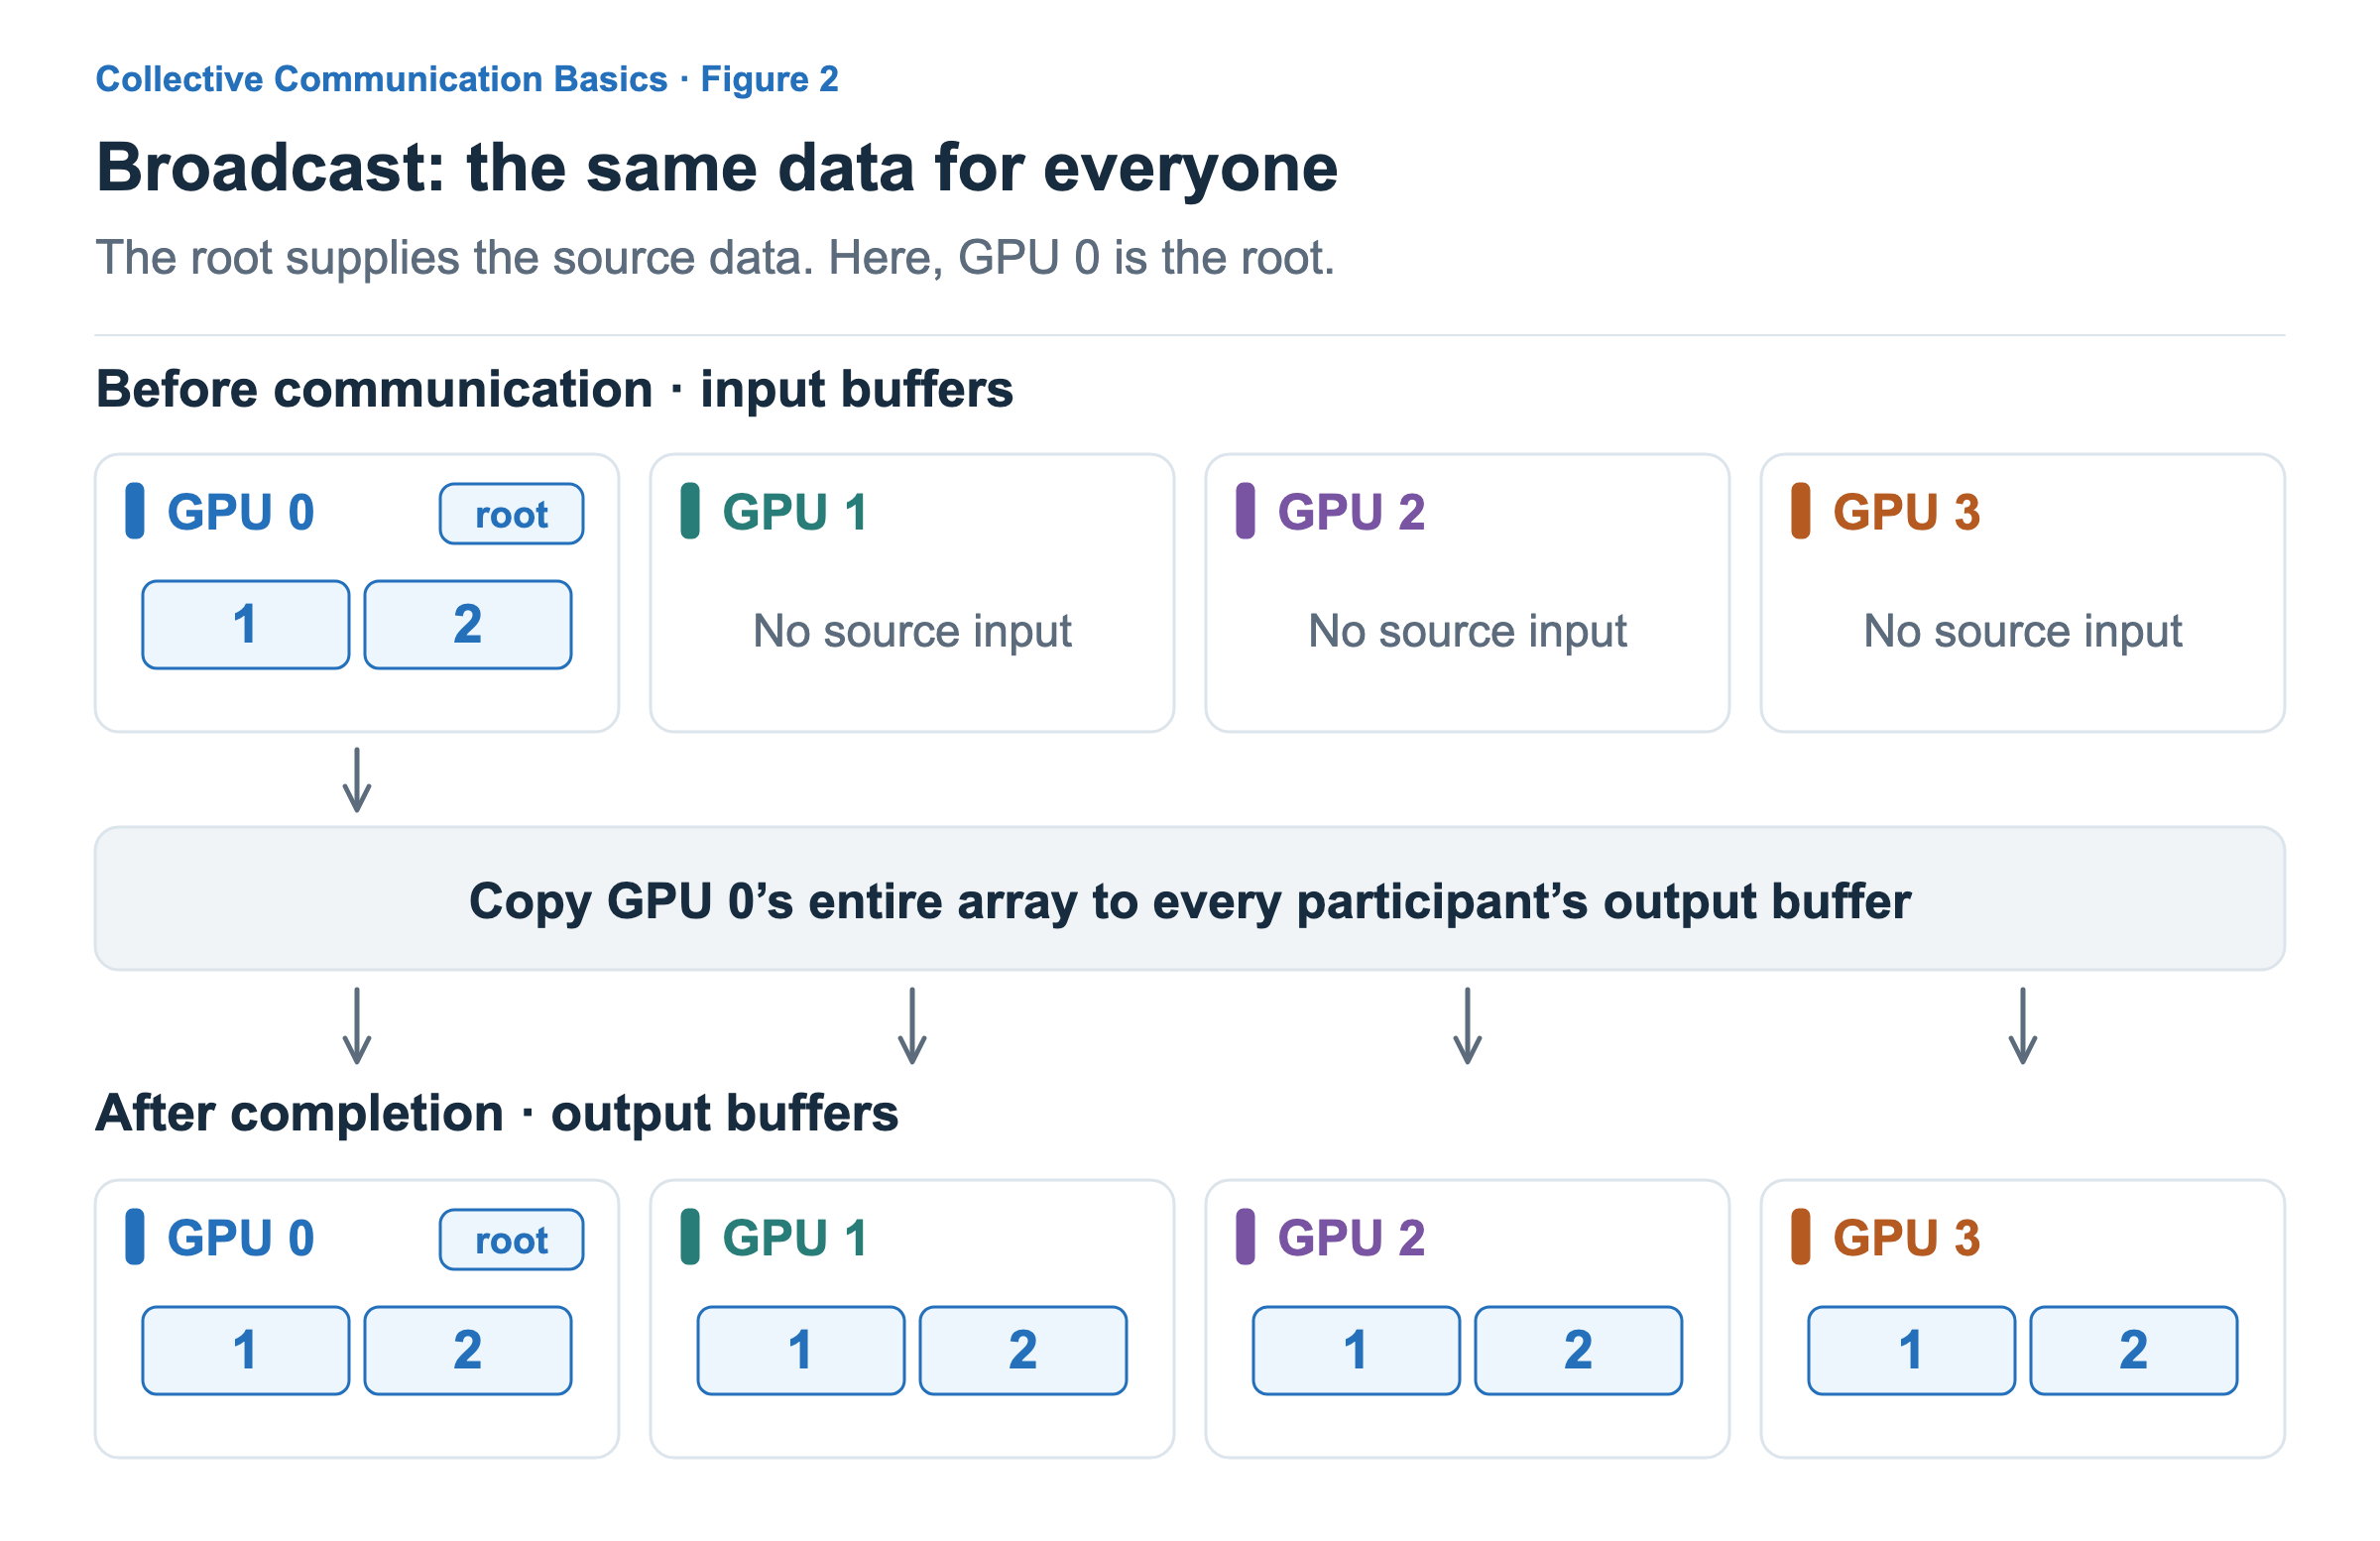
“No source input” on the other GPUs does not mean they do not participate. The root supplies the data for this operation, while the others participate with space prepared to receive it.
The root is itself a group member and holds the same data after completion. GPU 0 is not a special type of device that must be the root. The root is a role in this communication operation. If another GPU holds the original data, that participant can be chosen as the root.
The root’s input has two elements, so every GPU’s result also has two elements. Having four GPUs does not change the size of the array each receives.
Scatter: Distributing Chunks
Not every GPU needs the same complete array. If GPUs process different portions, we can partition and distribute the input. Scatter splits the root’s array into different chunks for the participants.
This time, GPU 0 has eight elements.
[1, 2, 10, 20, 100, 200, 1000, 2000]Dividing it into four two-element chunks gives [1, 2], [10, 20], [100, 200], and [1000, 2000]. We distribute one to each participant in rank order.
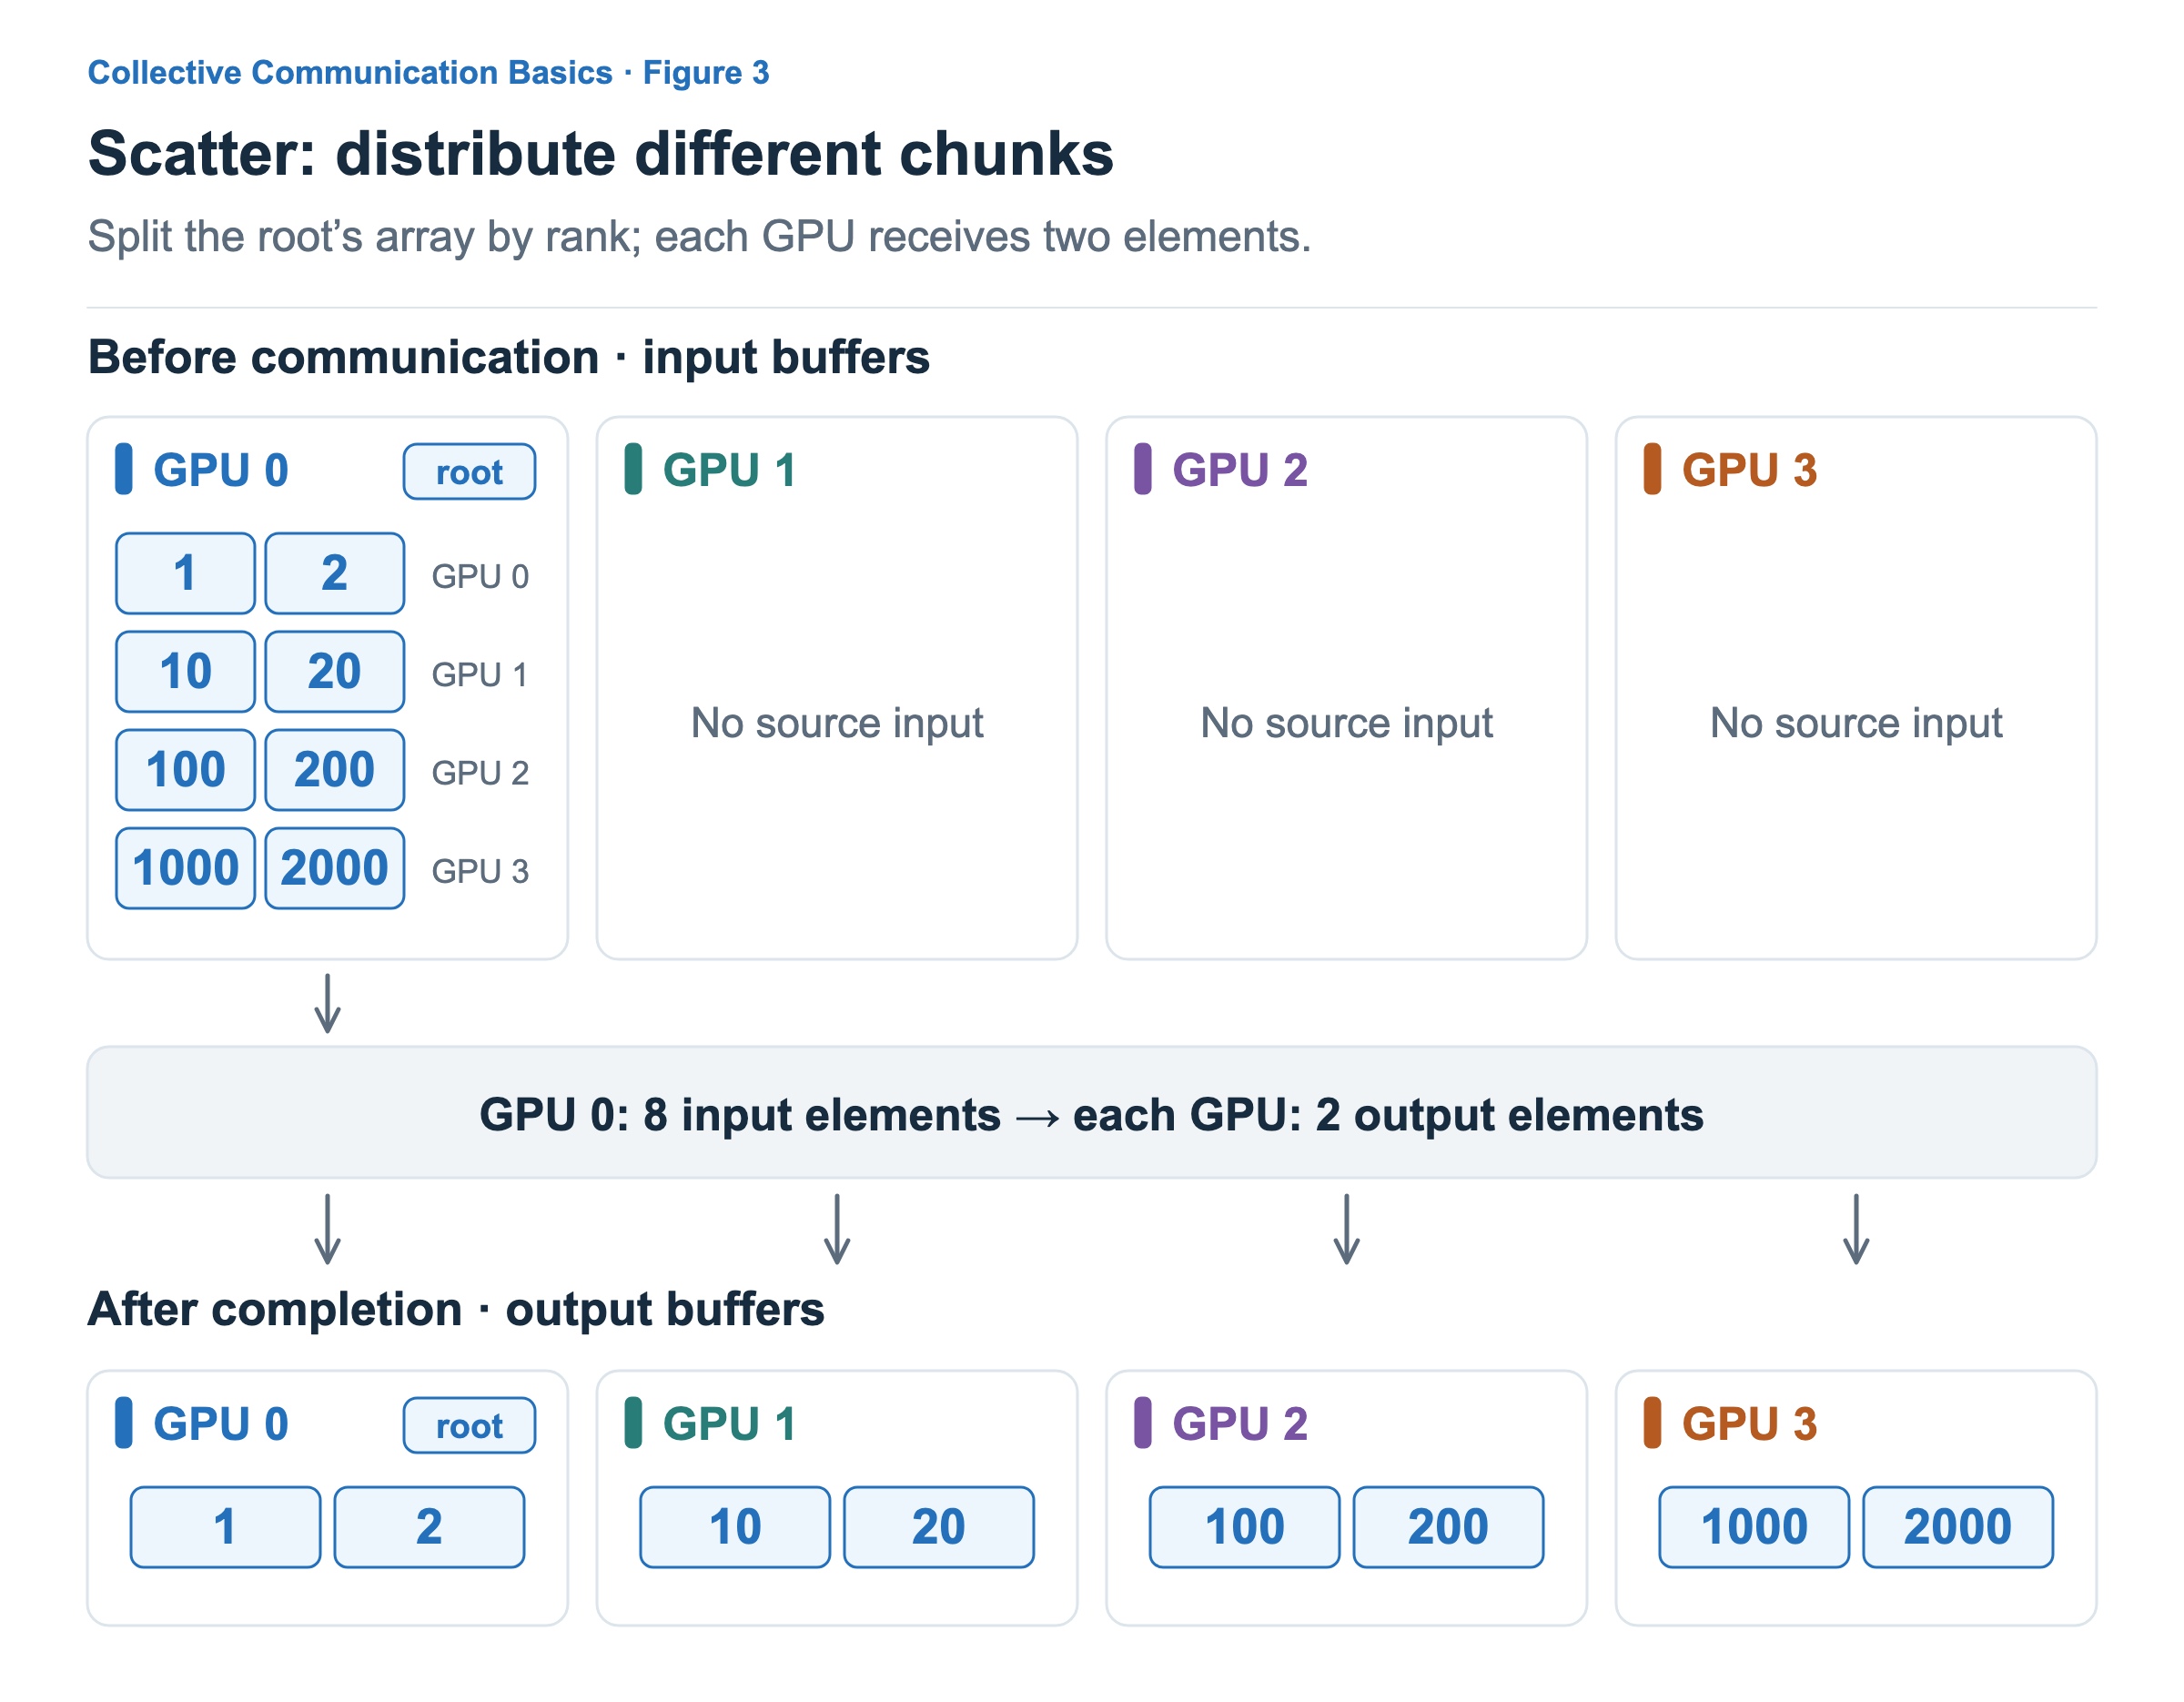
GPU 0 receives the first chunk, GPU 1 the second, GPU 2 the third, and GPU 3 the fourth. The root, GPU 0, also holds its assigned chunk. The input in the figure wraps across multiple rows for readability, but is a single array continuing from top to bottom.
Broadcast and Scatter both start at the root, but what participants receive differs. Broadcasting these eight elements gives every GPU all eight. Scattering them gives each GPU its assigned two elements.
“Splitting” describes the output placement. With separate input and output buffers as shown here, the root’s original input is not automatically erased. We will continue using the basic case of equal-sized chunks.
Gather: Collecting Chunks
Where Scatter distributes parts of an array from one location, Gather concatenates each participant’s array at the root. Consider it when results processed separately on each GPU must be read in order at one location.
Suppose GPUs 0–3 hold [1, 2], [10, 20], [100, 200], and [1000, 2000] respectively. Gather concatenates these arrays in rank order.
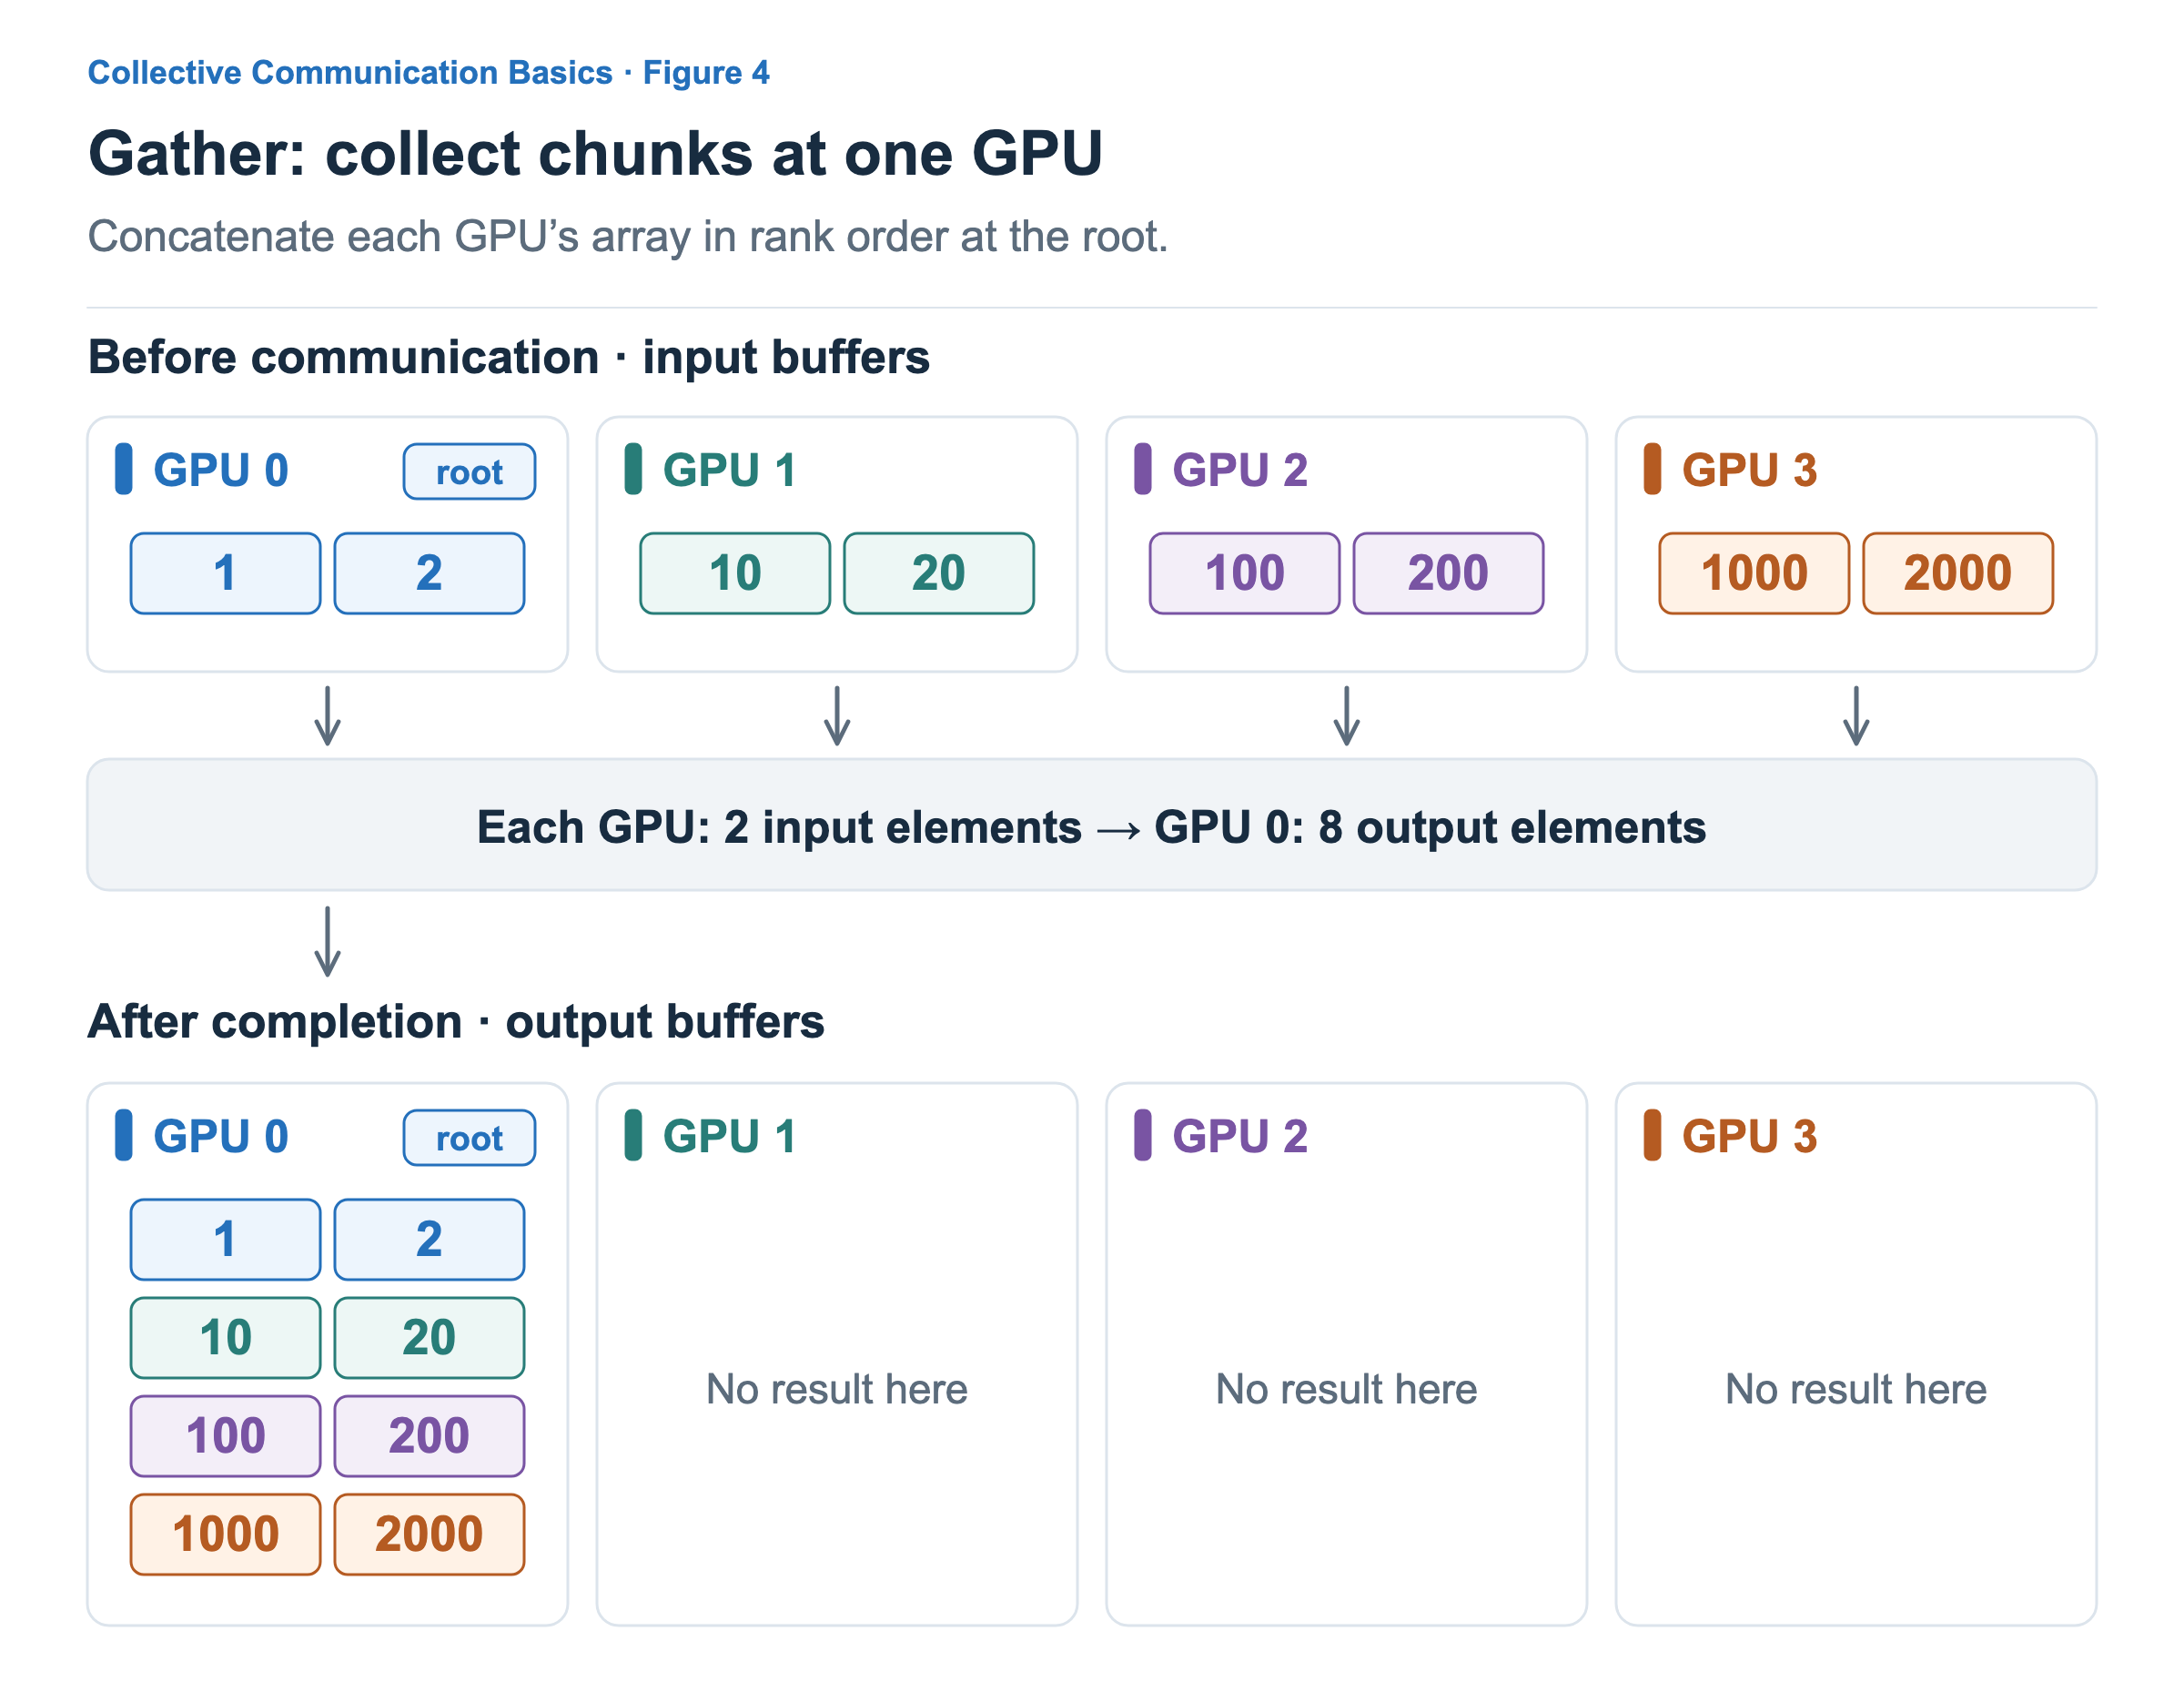
The root, GPU 0, obtains the eight-element array [1, 2, 10, 20, 100, 200, 1000, 2000]. Its own input [1, 2] is included. Arrays are placed at positions corresponding to their participants’ ranks, rather than being appended in arrival order.
Gather does not add values. It preserves the original elements and concatenates them into a longer array. Each GPU supplies two elements, so collecting the chunks from four GPUs produces eight elements.
“No result here” on the other GPUs means that the complete eight-element array is not produced there. Because the figure uses separate input and output buffers, each GPU retains its input. Collecting a result in one place is different from deleting existing data.
Reduce: Combining Corresponding Values
We may need to collect values from each GPU and add corresponding positions. That requires computation, rather than concatenation. Reduce combines values at corresponding positions using a specified operation and places the result at the root.
Use the same inputs as Gather, but combine them by addition. Add the first elements together, then the second elements.
Sum of first elements:  1 + 10 + 100 + 1000 = 1111
Sum of second elements: 2 + 20 + 200 + 2000 = 2222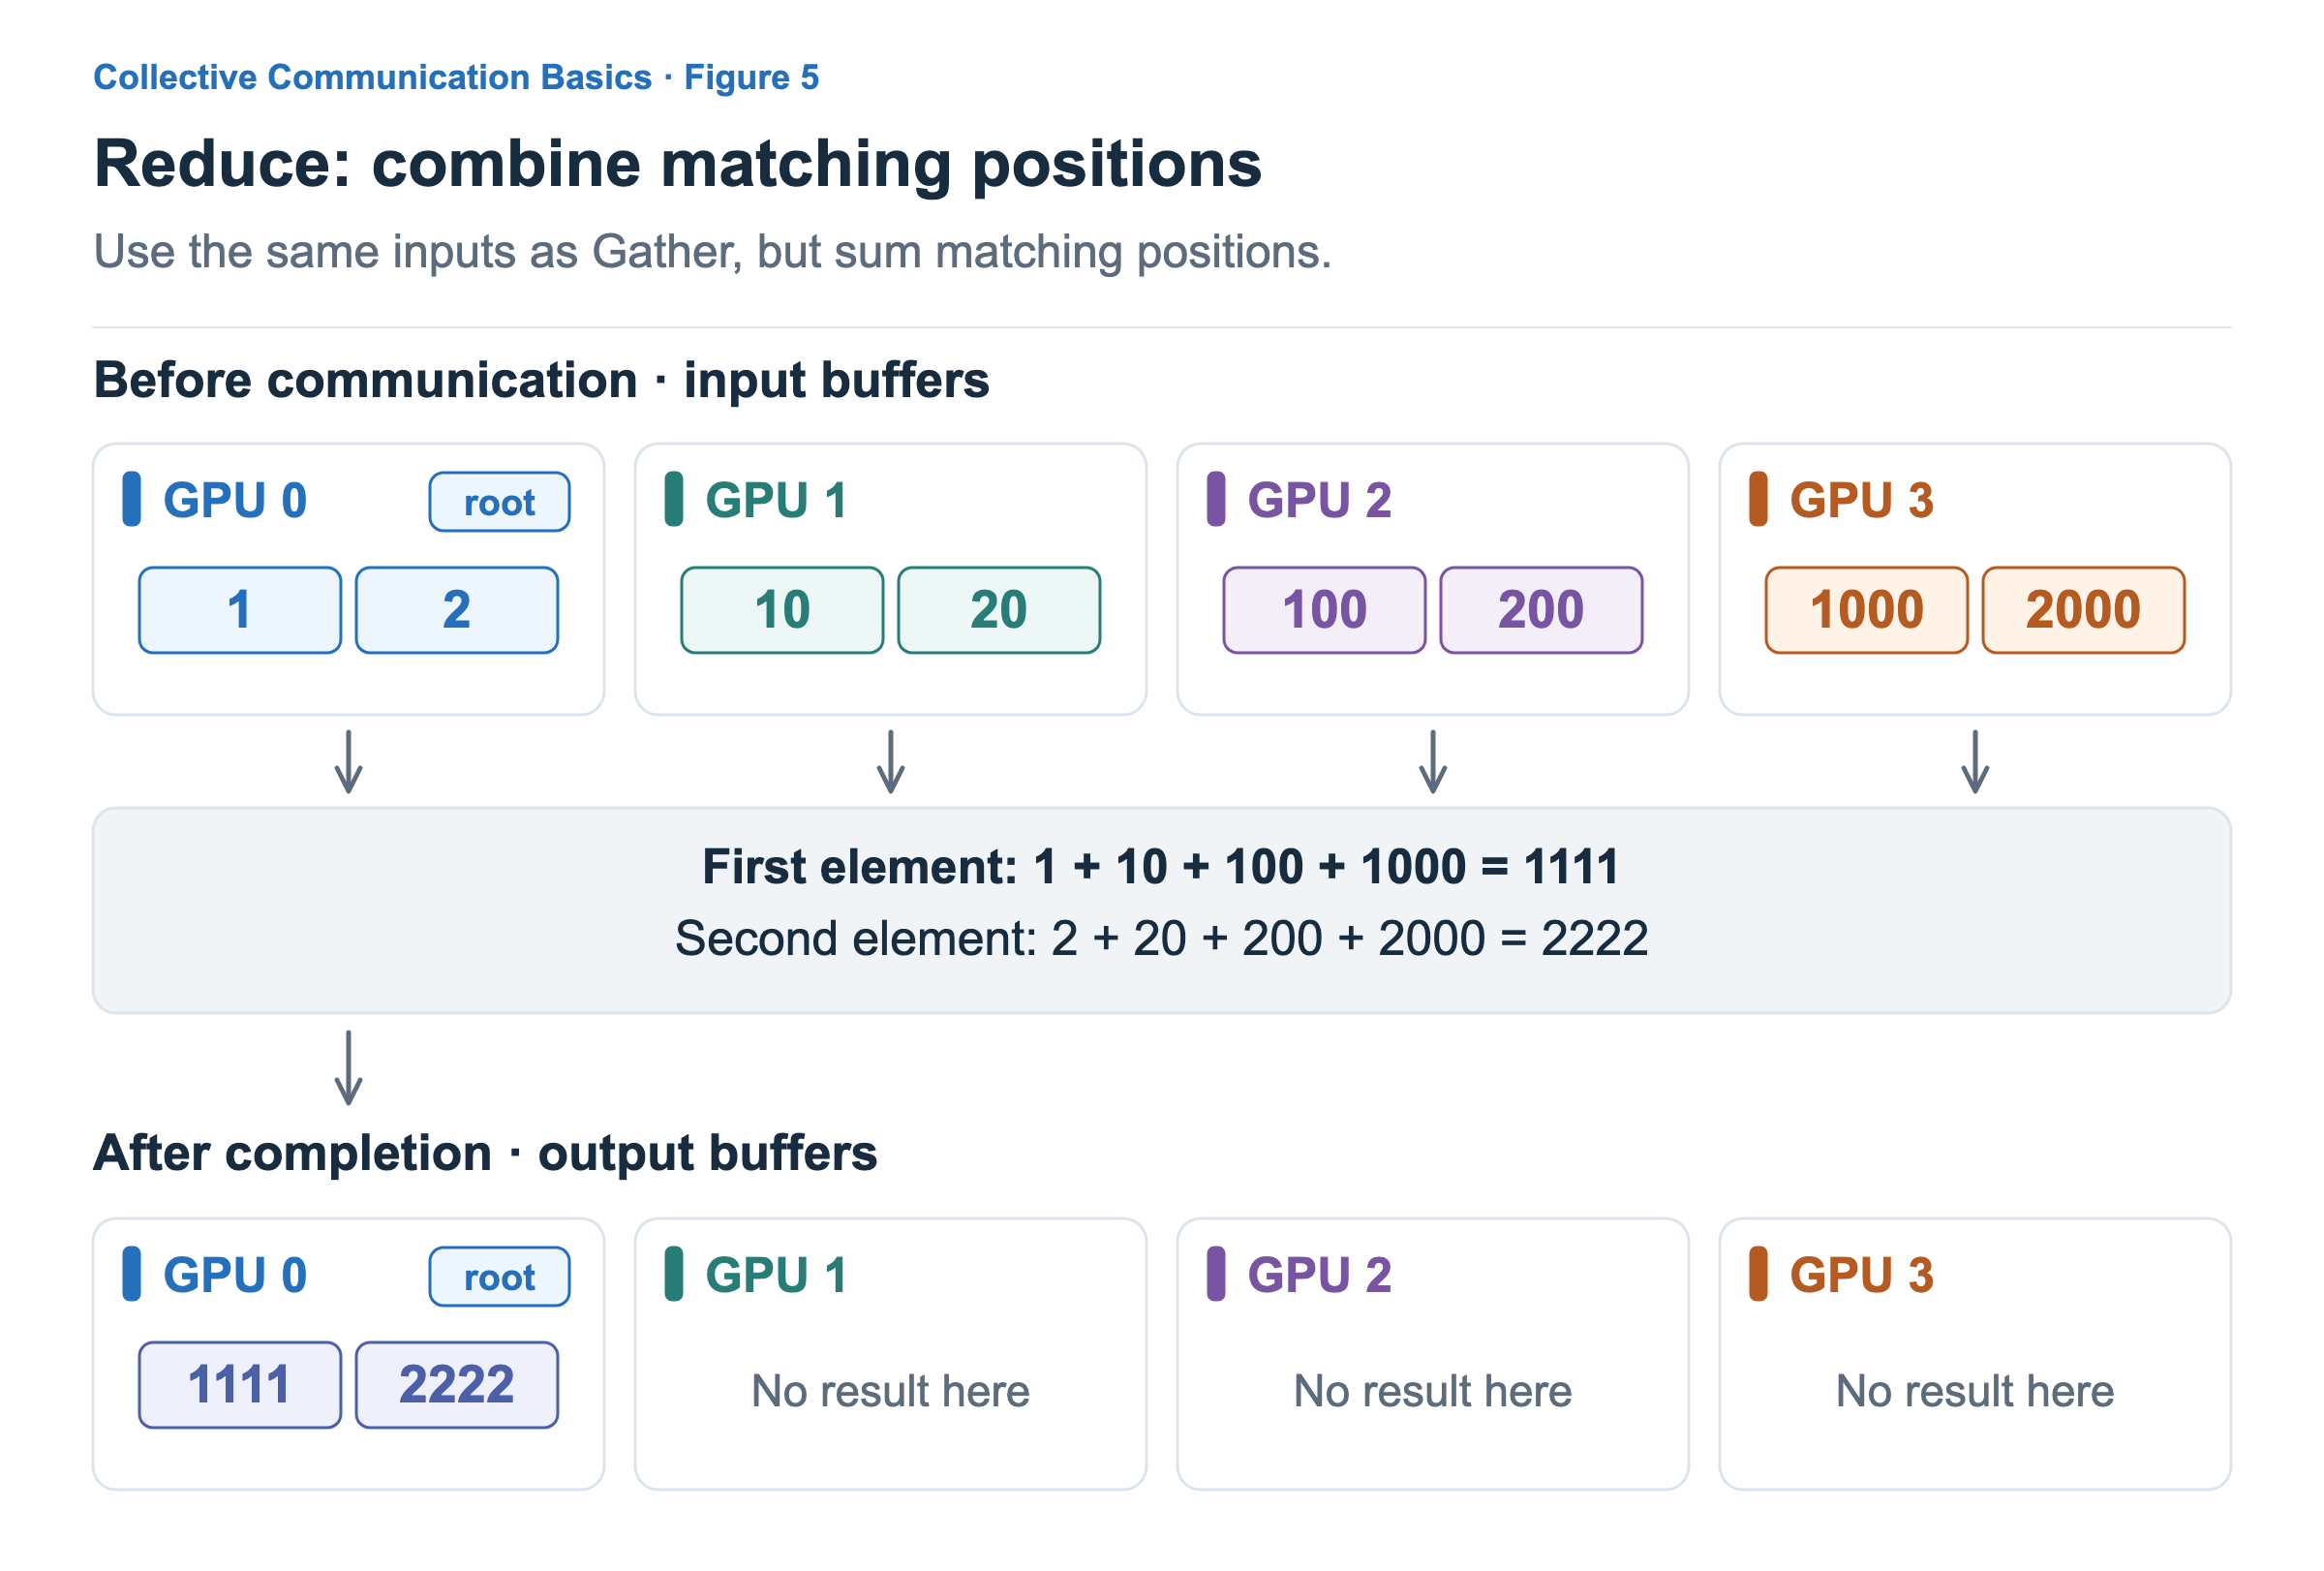
The root, GPU 0, holds [1111, 2222]. Each input array had two elements, and the result also has two. Reduce neither produces eight elements like Gather nor adds every value in the arrays into one number. It produces one result for each corresponding position.
This article uses addition, but Reduce can use other operations such as maximum or minimum. Participants must agree on the operation.
Distinguish the four operations by both the data’s contents and the result’s location. Broadcast copies the same array to everyone, while Scatter distributes different chunks. Gather concatenates chunks, while Reduce combines corresponding values through computation. The completed results of Gather and Reduce reside at the root alone.
What if every GPU needs the collected or reduced result? Alternatively, each might need only its own portion of a reduced result. Collective Communication: Combinations and Extensions continues with operations that share results, partition them, or exchange chunks by destination.